# The Demo That Parks One Time In Five
> I built a car that parks itself by scoring a menu of seven sentences. Then I took away its map, gave it ultrasonic sensors, and watched it get four times worse.
- Author: Olger Chotza
- Published: 2026-09-18
- Tags: llm, tooling, open-source
- Canonical: https://ochotzas.com/notes/the-demo-that-parks-one-time-in-five
I wanted to see what [option scoring](https://ochotzas.com/notes/the-normalisation-that-picked-the-worst-answer)
looks like when it has to do something real, so I built a car that parks itself. Every
tenth of a second it writes its sensor readings as text, a small language model scores
seven fixed actions, and the best one is executed. Nothing is generated. Nothing is parsed.
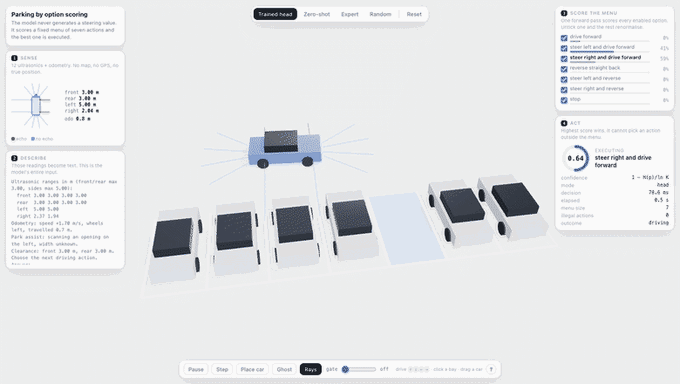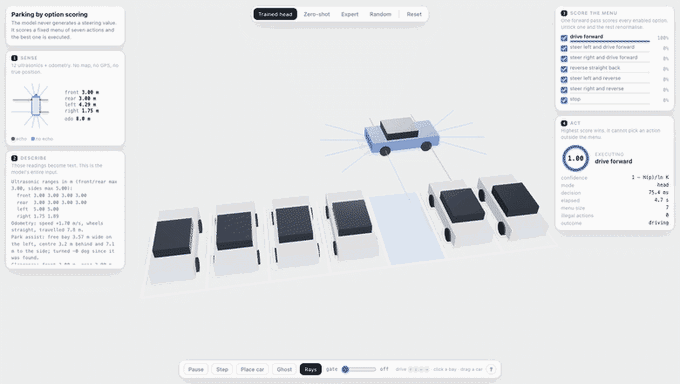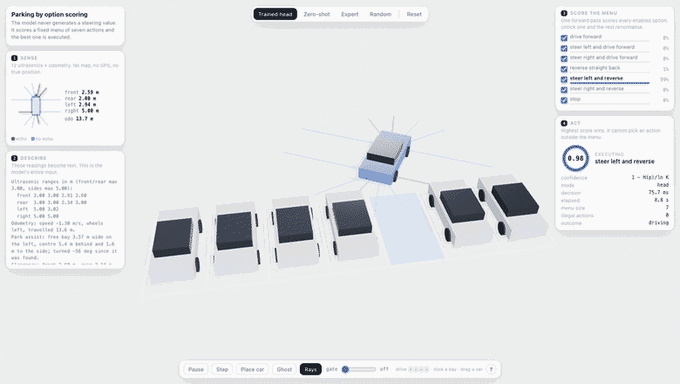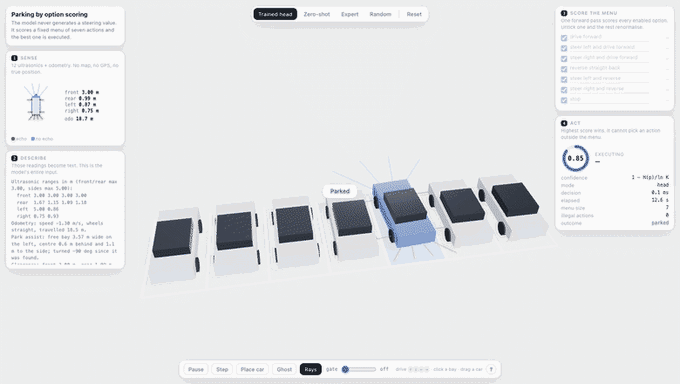
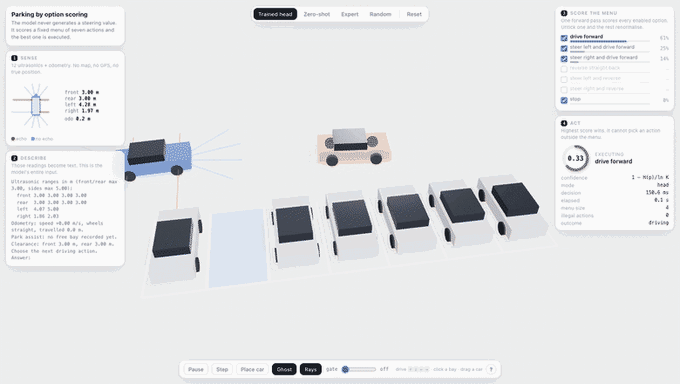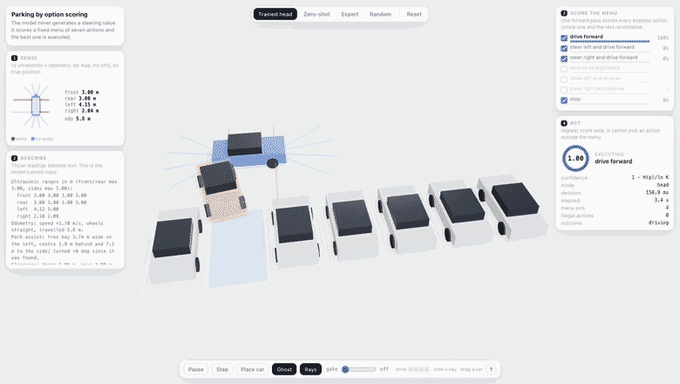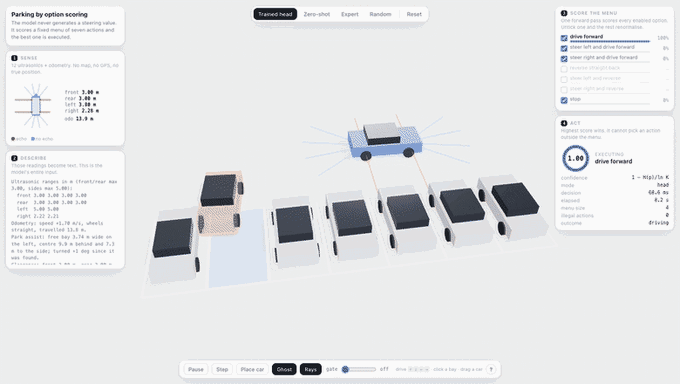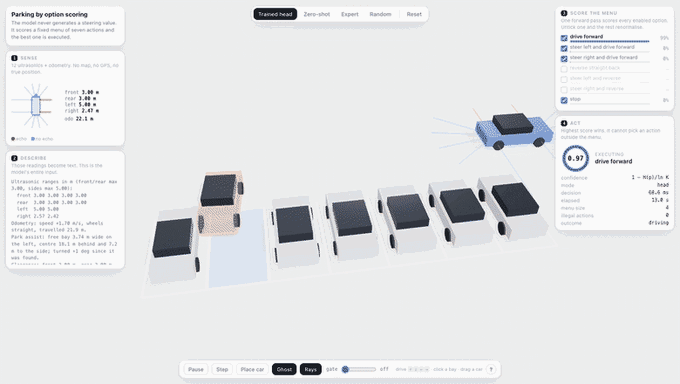
The whole loop: sensors, text, seven scores, one action. It drives past the row,
finds the gap, then arcs backwards into it.
The code is at [ochotzas/jev-park](https://github.com/ochotzas/jev-park). It runs on a
MacBook with a 0.5B model and no network. The rest of this is what I learned building it,
including the part where my numbers got dramatically worse and that turned out to be the
interesting bit.
## The menu is the whole trick
The car has exactly seven options:
```
drive forward · steer left and drive forward · steer right and drive forward
reverse straight back · steer left and reverse · steer right and reverse · stop
```
Each tick, the context is prefilled through the model once, its KV cache is expanded
across the seven options, and all of them are scored in a single forward pass. Softmax the
scores and you have a distribution over actions you wrote yourself.
The guarantee this buys is narrow and absolute: **the car cannot take an action that does
not exist.** Across every run in the repo — including the deliberately awful ones — the
illegal-action counter reads 0. There is no JSON parser anywhere, no schema validation, no
retry, because there is nothing that could come back malformed.
It is worth being precise about what that does *not* buy you. A menu guarantees the answer
is *in* the menu. It says nothing about whether it's the right item. My zero-shot baseline
drives directly into a parked car while emitting perfectly valid actions.
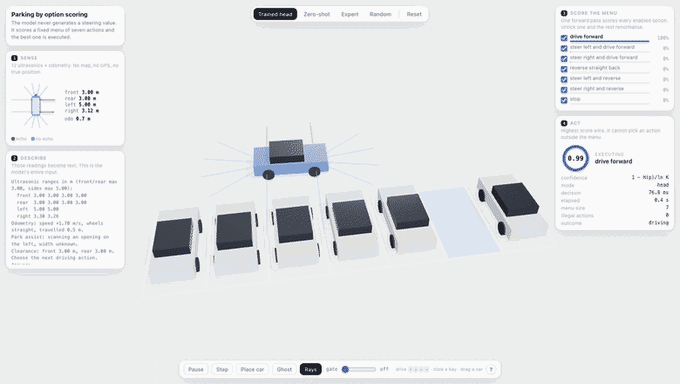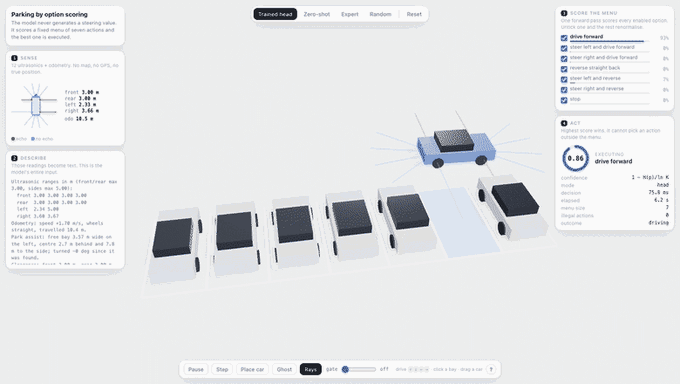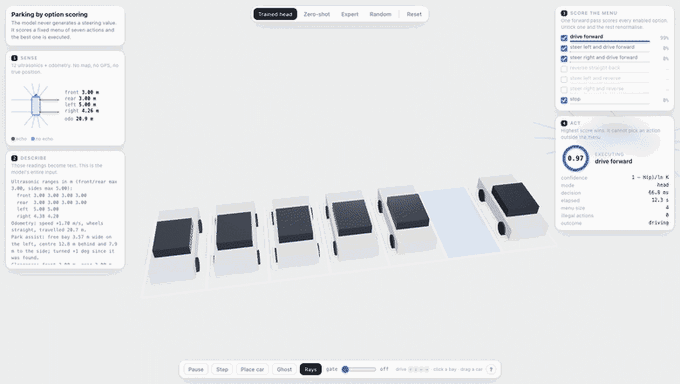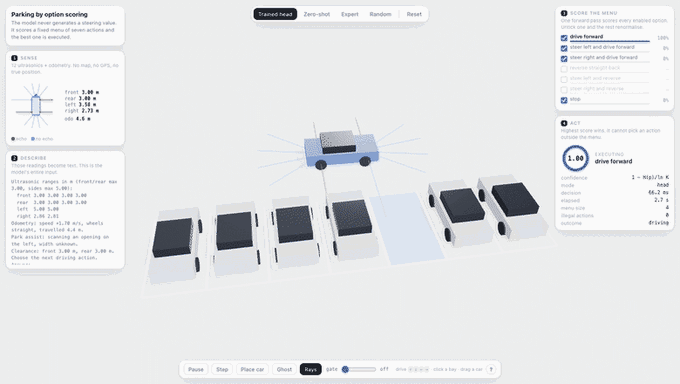
Because the menu is data rather than code, you can edit it while the car is driving:
Unticking the three reverse actions mid-run. Menu size drops to four, the
remaining probabilities renormalise, and the car — with no way to back in — drives
straight past the bay and strands itself.
Nothing is retrained or re-prompted there. The head scores whatever list it's handed. Watch
the confidence while it happens: it stays pinned near 1.00 the entire time the car is
failing, because confidence is normalised over *the options you passed*, not over the world.
## Giving it real senses
The first version cheated. Its text said things like *"the bay is 4.6 m behind you and you
are 88° off square"* — which is the answer, written out. No car knows that. So I replaced
it with what a real park-assist system actually has:
- **Four front and four rear ultrasonics**, 3 m range, at ±12° and ±40°, exactly where the
bumper sensors sit on a real car.
- **Two side sensors per side**, 5 m range. These are the ones that find the space.
- **Odometry and integrated yaw**, both noisy.
- **No map, no GPS, no true position.**
Ranges come from ray casts against the parked cars, the bay wall and the kerb, with
Gaussian noise and a 1.5% dropout rate. One detail I got wrong twice: a sensor that hears
nothing back should report *no echo*, not a plausible-looking maximum distance. I was
adding noise to the no-echo value and then clamping it, which made detection flicker.
**Finding the bay works the way a real car does.** Driving forward past the row, the
front-left sensor echoes off each parked car and returns nothing where a bay is free. That
run of silence, measured against the odometer, is the gap. It finds it 24 times out of 24.
It also measures it wrong, in a way I decided to keep. The ray clears the neighbour's
corner before the car is level with it, so a 2.8 m bay measures about 3.5 m. That's a
genuine geometric bias in real SPA systems, and calibrating it out felt like cheating. The
model learns from the biased number.
The part I like most: once the car is past the bay, **the bay is no longer visible to any
sensor.** So the estimate is carried by dead reckoning — the remembered gap centre rotated
and translated each tick by the car's own noisy odometry, accumulating drift. That is what
it steers by while reversing, which is why the text reads:
```
Park assist: free bay 3.57 m wide on the left, centre 4.1 m behind
and 1.1 m to the side; turned -31 deg since it was found.
```
Not a position. A memory, decaying.
## What perception cost
Here is the honest table. The expert is a scripted controller with ground-truth access —
the demonstrator that generated the training data, standing in for a human driver who can
see. **In-dist** is the training start distribution; the OOD columns randomise position and
then heading.
| Policy | In-dist | OOD lane | OOD any |
|---|---|---|---|
| Expert (privileged teacher) | 100% | 67.5% | 37.5% |
| Trained head, sensors only | **20%** | 8% | 4% |
| Same numbers, no language model | 10% | 0% | — |
| Zero-shot likelihood | 0% | — | — |
Twenty percent. The demo parks one time in five.
The earlier oracle version managed 96.7%. Removing the map cost almost all of it — and
here is the part I did not expect:
| Input | Held-out action accuracy | Park rate |
|---|---|---|
| Oracle error vector | 92.4% | 96.7% |
| Ultrasonics + odometry | 86.0% | 20% |
**A six-point drop in per-step accuracy produced a five-fold drop in competence.** Parking
is about 140 sequential decisions, and small per-step errors compound into a car that
misses the bay. Open-loop accuracy is a comforting number that does not predict whether the
thing works.
The same effect answers the obvious sceptical question — *is the language model doing
anything, or would a few floats do?* I trained a small MLP on exactly the same perceived
values as numbers. It reaches **86.2%** held-out accuracy against the head's 86.0%.
Statistically identical. It parks **10%** against the head's 20%, and 0% out of
distribution. Same accuracy, half the competence.
## Watching two policies diverge
The clearest way to see what the trained head buys is to run it against untrained
likelihood scoring from an identical start:
Blue is the trained head. Translucent orange is zero-shot — same encoder,
same menu, same 80 ms, no trained head. It veers into the parked cars within seconds.
Same model, same seven sentences, same forward pass. The only difference is whether the
score comes from "what text is likely to follow" or from a head trained on what actually
parks. That's the entire argument for putting a trained head on a frozen encoder rather
than prompting harder.
## The finding that made me rewrite a paragraph
I had written, confidently, that the confidence number is uncalibrated but still useful —
that its *ordering* holds, so thresholding on it filters bad decisions even if the values
are inflated. With the oracle input that was true: ECE 0.106, and a clean monotone curve
from 0.44 agreement at low confidence to 0.90 at high.
Then I measured it on the sensor version:
| Confidence bucket | n | Mean confidence | Actually agreed |
|---|---|---|---|
| 0.6–0.7 | 134 | 0.645 | 0.373 |
| 0.7–0.8 | 108 | 0.749 | 0.324 |
| 0.8–0.9 | 178 | 0.857 | 0.315 |
| 0.9–1.0 | 1,708 | 0.983 | **0.296** |
Agreement is flat at roughly 0.30 across every bucket, and *lowest* in the most confident
one. ECE 0.613. The ordering isn't weak, it's gone. Eighty-seven percent of decisions land
in that top bucket, where the model is as good as a coin-flip relative to its own teacher
and says 0.98 about it.
So the confidence gate I built — refuse to act below a threshold, hand back control — does
not work on the harder task. It worked on the easy one, which is exactly how you end up
shipping a safety mechanism that has quietly stopped being one. Normalised entropy measures
how *peaked* a distribution is, not whether it's peaked on the right option, and a model
can be consistently, confidently wrong. Closing that needs training against outcomes, which
no likelihood or cross-entropy objective gives you.
I went back and rewrote the README.
## Three bugs worth the time
**The controller that oscillated forever.** My scripted expert drove to a staging point,
then reversed. Except "am I staged?" was recomputed every tick, so reversing dropped the
car back over the line, which flipped it to forward, which pushed it over again. It sat
there vibrating at 0% success until I made the decision latch.
**Imitating failure.** I widened the training distribution to include harder start poses
and everything got *worse* — in-distribution fell from 100% to 67%. The expert only parks
67% of the time from those poses, so half my new demonstrations were trajectories heading
for a collision, and the model dutifully learned them. Keeping only episodes that ended
parked — 157 of 300 — recovered it and roughly doubled OOD performance. Imitation learning
means imitating, including the crashes.
**Threads and Metal.** Running model inference in `asyncio.to_thread` fails with
`There is no Stream(cpu, 0) in current thread` — MLX streams are thread-local. Decisions
run on the event loop instead, which is fine at 80 ms against a 100 ms tick.
## Where it stands
It is a demo that parks one time in five, and I think that's a more useful artefact than
one that parks every time by being handed the answer. The mechanism is sound and measured:
7,000 lines of nothing-can-be-malformed, 25 tests, every number in the README regenerable
by a command in the README.
What I'd try next, in order: last-token pooling instead of mean-pooling the context, since
a long sensor description dilutes the few numbers that matter and that's a one-line change;
proper DAgger, so the head is corrected on states it actually visits rather than the ones
its teacher visits; and a real planner for the expert, because 37.5% on random headings is
the ceiling the student is chasing.
The thing I'll carry to the next project is smaller than any of that. **The metric that
looked fine was the one that lied.** 86% accuracy, 0.98 confidence, and a car in the
bushes.
---
Code, numbers and the 3D demo: [ochotzas/jev-park](https://github.com/ochotzas/jev-park).
Built on Apple silicon with MLX and Qwen 0.5B.